About
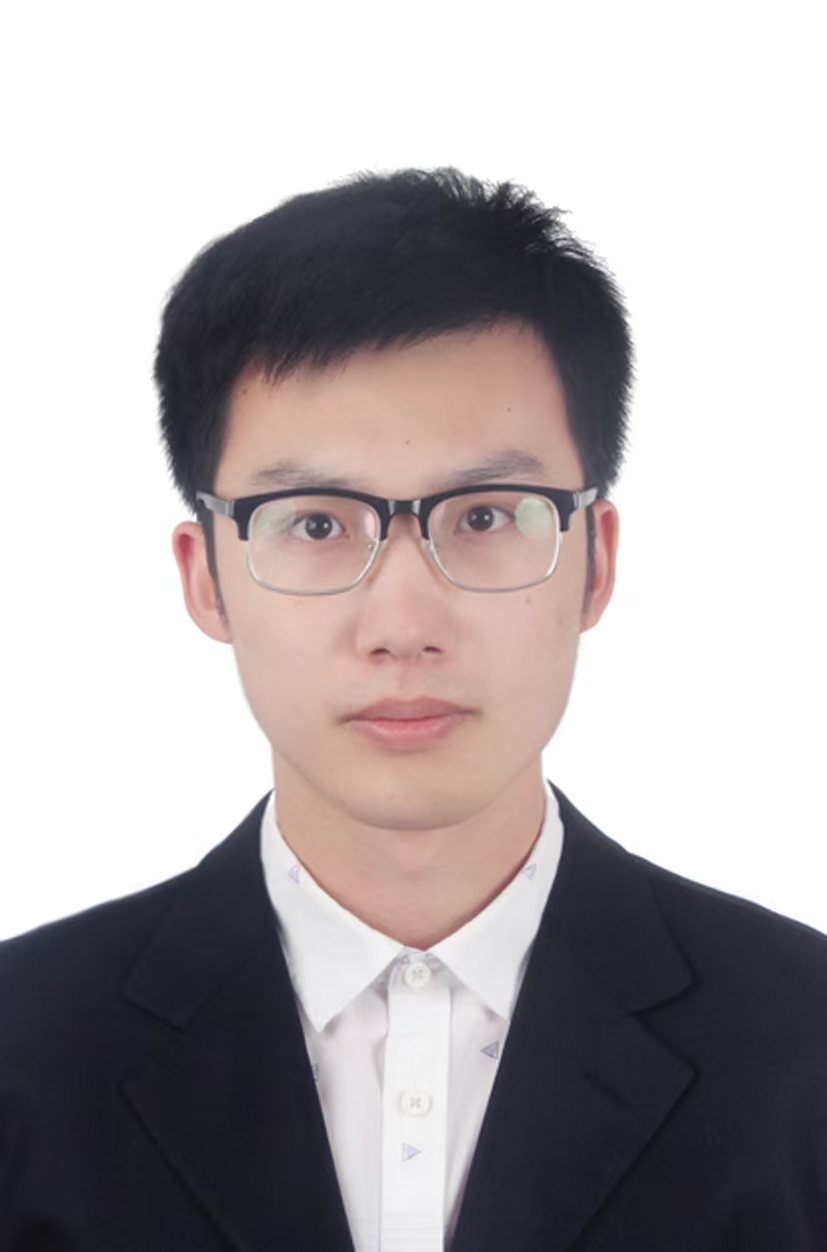
I am an AI Researcher at JD Explore Academy in Shanghai. My research focuses on Embodied AI, Multimodal Foundation Models, 3D Vision, and Reinforcement Learning. I am interested in building intelligent agents that can perceive, reason, plan, and act in complex physical environments.
I received my M.Eng. in Control Science and Engineering and B.Eng. in Automation from Tongji University. I am always open to research discussions and collaboration. Feel free to drop me an email.
Research Interests
Education
Tongji University
- M.Eng in Control Science and Engineering, Sep. 2021 - Jun. 2024
- Mentor: Prof. Chengju Liu (Google Scholar) and Prof. Qijun Chen (Google Scholar)
- National Scholarship, Ministry of Education of China, 2023
Tongji University
- B.Eng in Automation, Sep. 2017 - Jun. 2021
Experiences
 May 2026 – Present
AI Researcher @ JD Explore Academy
Focus on Embodied AI and Physical World Pretraining.
 May 2024 – May 2026
AI Researcher @ Alibaba DAMO Academy
Focus on Embodied AI and spatial intelligence.
 May 2023 – Sept. 2023
Research Intern @ SenseTime
Focus on MLLM and multimodal generalization.
 Jan. 2020 – June 2020
Research Intern @ CASIA
Focus on neural architecture search (NAS).
Publications
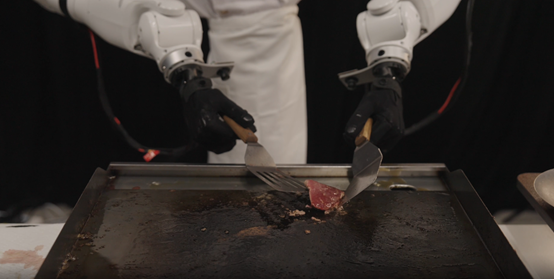
RynnBrain 1.1: Towards More Capable and Generalizable Embodied Foundation Model
RynnBrain 1.1 evolves embodied models and builds cross-robot VLA.
It tops benchmarks and beats mainstream VLAs in real robot tests.
DAMO Technical Report
Rynnbrain: Open embodied foundation models
A unified embodied foundation model integrating comprehensive egocentric understanding, diverse spatiotemporal localization, physically grounded reasoning, and physics-aware planning.
DAMO Technical Report
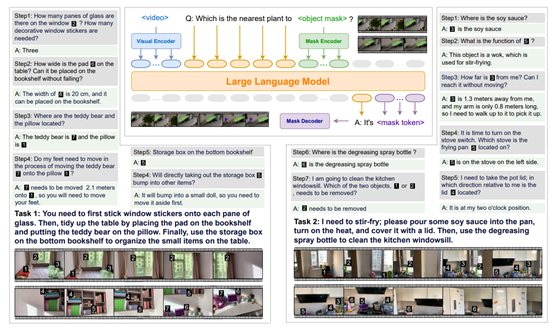
RynnEC: Bringing mllms into embodied world
A region-centric video paradigm for embodied-agent cognition, enabling fine-grained perception and more precise physical interactions.
DAMO Technical Report
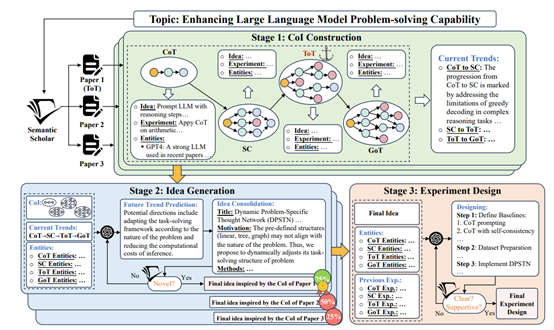
Chain of Ideas: Revolutionizing Research Via Novel Idea Development with LLM Agents
Existing idea-generation LLM methods lack structured literature utilization. We propose Chain-of-Ideas agent and Idea Arena; it surpasses baselines and achieves human-level ideas with low cost.
EMNLP 2025
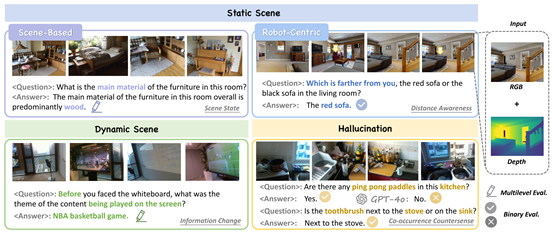
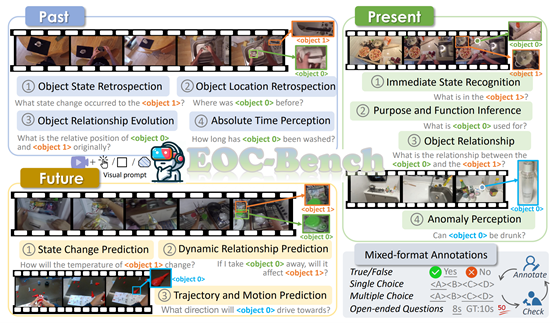
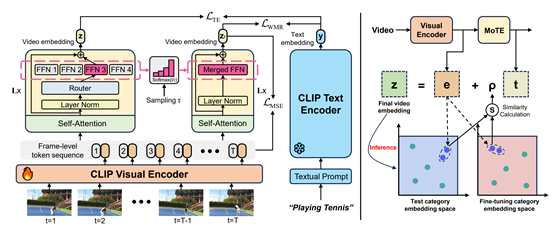
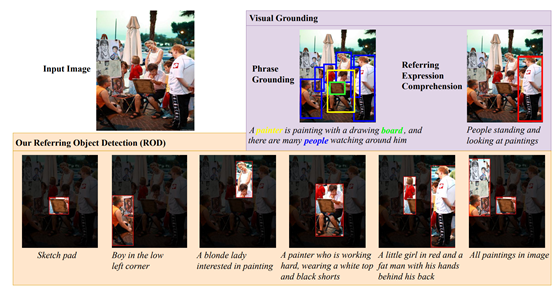
INSTRUCTDET: DIVERSIFYING REFERRING OBJECT DETECTION WITH GENERALIZED INSTRUCTIONS
We propose InstructDET, leveraging foundation models to construct InDET with diverse instructions for referring object detection.
The pipeline enables automatic data expansion from any images equipped with bounding boxes.
ICLR 2024
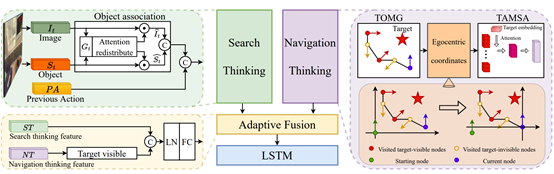
Search for or Navigate to? Dual Adaptive Thinking for Object Navigation
We propose DAT, a dual adaptive reasoning paradigm distinguishing searching and navigating stages in object navigation.
It dynamically switches strategies leveraging object association and target location awareness.
ICCV 2023
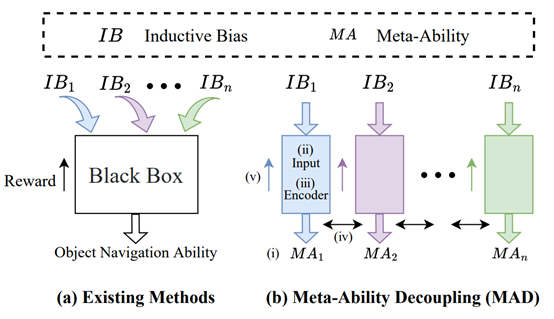
Multiple Thinking Achieving Meta-Ability Decoupling for Object Navigation
We propose a meta-ability decoupling paradigm to integrate object navigation methods.
Based on it, the multiple thinking model decouples meta-abilities and adopts a collaboration module, establishing new interpretability for object navigation.
ICML 2023
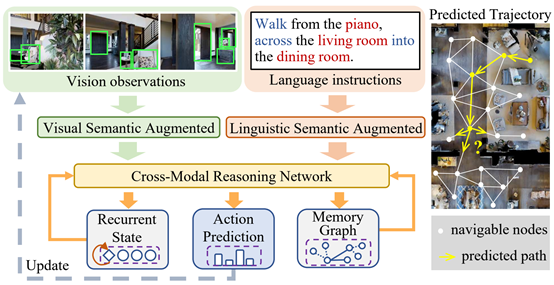
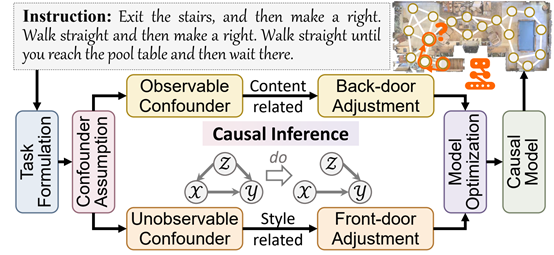
A Dual Semantic-Aware Recurrent Global-Adaptive Network for Vision-and-Language Navigation
Vision-and-Language Navigation suffers from insufficient cross-modal semantic mining and inadequate differentiated visual memory, so we construct a dual semantic-aware recurrent global-adaptive network equipped with dual semantic modules and innovative memory mechanisms.
IJCAI 2023
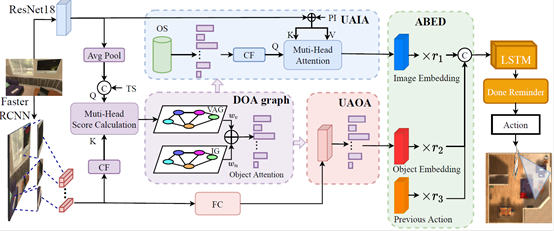
Unbiased Directed Object Attention Graph for Object Navigation
We propose a directed object attention graph to alleviate attention bias for object navigation. We introduce two unbiased adaptive attention mechanisms and a compact adaptive branch energy distribution module for feature distinction.
ACMMM 2023
Selected Honors & Awards
- DAMO Academy's Excellence Award, Alibaba DAMO Academy, 2025.
- National Scholarship, Ministry of Education of China, 2023.
- Excellent Graduation Project, Tongji University (Quota: 2 recipients per year), 2021.
- Champion, Home League, RoboCup China Open, 2021.
- National Second Award, Artificial Intelligence Challenge Track, China Computer Design Competition, 2020.
- First Class Scholarship, Tongji University, 2018, 2020, 2022.
Academic Services
Conference Reviewer:
Conference on Computer Vision and Pattern Recognition (CVPR)
International Conference on Computer Vision (ICCV)
European Conference on Computer Vision (ECCV)
Conference on Neural Information Processing Systems (NeurIPS)
International Conference on Learning Representations (ICLR)
International Conference on Machine Learning (ICML)
International Conference on Robotics and Automation (ICRA)
International Conference on Intelligent Robots and Systems (IROS)
Journal Reviewer:
Transactions on Pattern Analysis and Machine Intelligence (TPAMI)
Transactions on Neural Networks and Learning Systems (TNNLS)
Transactions on Circuits and Systems for Video Technology (TCSVT)
Transactions on Multimedia (TMM)